About
I am a PhD candidate in Statistics at Texas A&M University, graduating in May 2027.
My research focuses on statistical identifiability, Bayesian inference, and computational model validation. I study what can be learned from incomplete or imperfect observations, how to detect unreliable estimates, and how to quantify uncertainty in downstream predictions and decisions.
My work combines statistical methodology, Monte Carlo simulation, and applied modeling across scientific and economic problems.
Selected work
Research methods and computational studies.
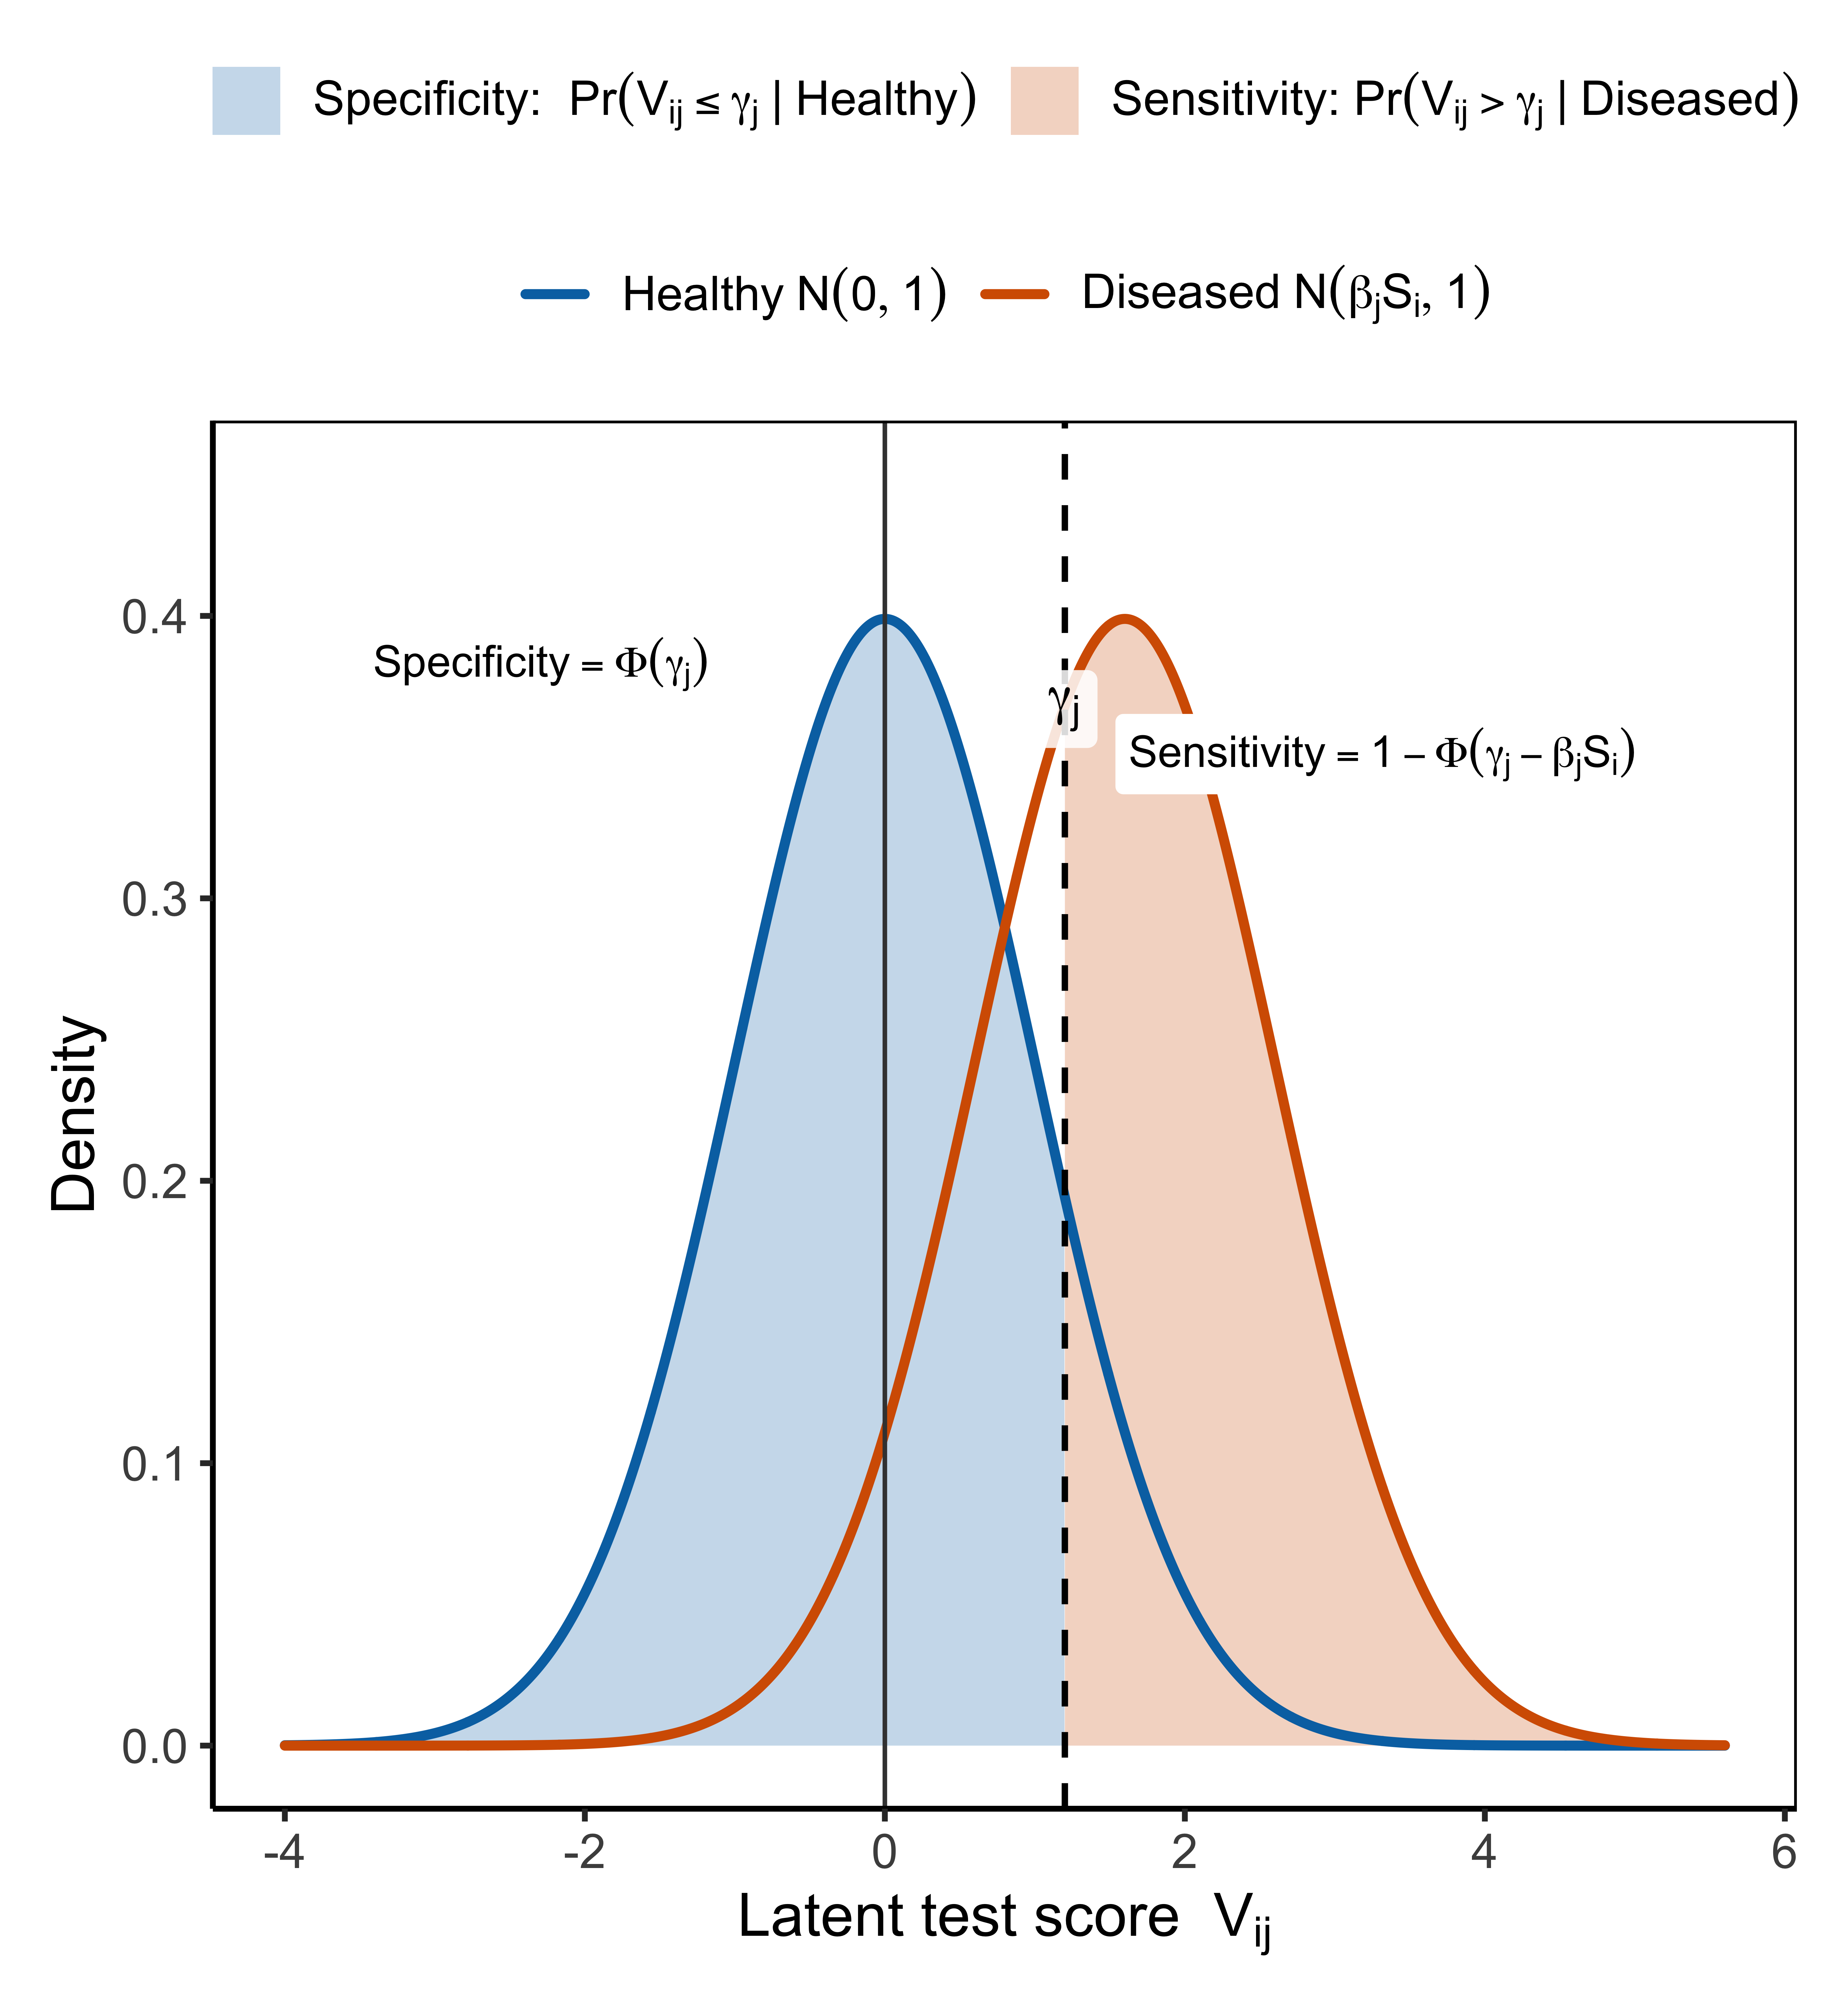
Bayesian model for estimating diagnostic accuracy and prevalence without a gold standard, incorporating continuous latent severity. Studied identifiability and model behavior using MCMC, parameter-recovery simulations, and a Strongyloides reanalysis.
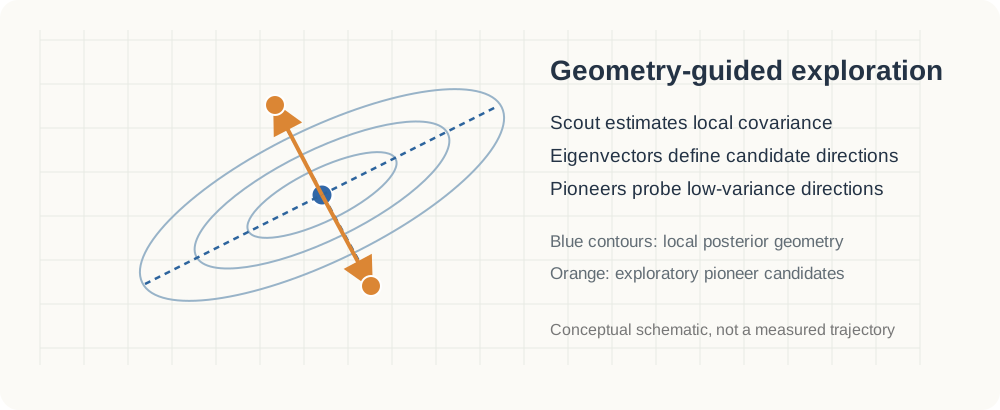
Exploratory comparison of coordinated proposal strategies for difficult posterior distributions. Benchmarks showed occasional improvements, but no consistent advantage over conventional methods.
Additional work
A/B testing
Experimental design and treatment-effect estimation
Publications
Collaborative papers. Role on each paper is listed after the citation. Dissertation chapters are in preparation and are not listed as publications.
Guela, G.K., Laine, C.G., Gontao, P., Gomsu Dada, C.O., Abiba, H., Desire, D.P., Mbacham, W., Garcia-Gonzalez, D., Vection, S., Gillece, J.D., Kim, M., Johnson, V.E., Foster, J.T., Wade, A., Arenas-Gamboa, A.M.
Nature Communications 16, 11600 (2025). Role - formal analysis, visualization, writing review and editing.
Wang, J., Zhang, W., Liu, X., Kim, M., Ke, Z., Tsai, R.
BMC Biology 21, 30 (2023). Role - statistical analysis.
Peng, H., Xu, H., Wu, J., Li, J., Wang, X., Liu, Z., Kim, M., Jeon, M.S., Zhang, K.K., Xie, L.
Nutrients 14(12), 2545 (2022). Role - statistical analysis.
Experience
- Undergraduate probability, estimation, testing, regression, and computation in R.
- Credible intervals for predictive models, so uncertainty was attached to the forecast rather than reported separately.
- Repeatability and reproducibility studies to quantify measurement variability for product validation.
- Predictive models from chemical composition to transmission-fluid performance.
- High-dimensional regression and clustering on DNA methylation data.
- NHANES analysis of dietary risk factors for hypertension in pregnancy.
- Developed the R package nhanesGraph for searching public-use continuous NHANES files and downloading them from the current CDC XPT URLs, 1999-2000 through August 2021-August 2023. Not an official CDC tool.
- Analysis contributed to peer-reviewed papers listed below.
Dissertation
Chapter I — Prevalence without a gold standard.
Prevalence and diagnostic accuracy are estimated from imperfect tests and heterogeneous study designs. We characterize when those parameters are identified, then estimate them with Bayesian latent-class and latent-severity models, checked by parameter-recovery simulations.
Chapter II — Cost burden.
Prevalence is an intermediate. The target is a distribution over economic loss, obtained by propagating the Chapter I posterior together with uncertainty in population and cost inputs.